← Back to blogPostgreSQL
What Is the N+1 Query Problem? How to Detect and Fix It
The N+1 query problem makes your app run one query per record instead of one total, quietly multiplying database load until pages crawl. Here’s how to spot it across Rails, Django, Hibernate, and Prisma, detect it in Postgres and MySQL, and fix it with eager loading, better SQL, or caching.
Readyset
2024-02-14 · 18 min read
The N+1 query problem occurs when an application runs one query to fetch a list of records, then one additional query for each record to load its related data. A page showing 100 books with their authors fires 101 queries instead of 1. The result is slow response times and heavy database load.
Imagine you're running a popular e-commerce online bookstore that offers a vast collection of titles and authors to a growing user base. However, you've noticed a troubling trend over the past few months: the website is gradually slowing down, especially during peak hours when users browse various book categories. After an initial investigation, you find that the cause of the slowdown isn't an increase in user traffic or a lack of server resources. Instead, it's rooted in the very foundation of how your application interacts with your database.
The culprit? N+1 query problems. As more users navigate your site, more requests are made to the database to fetch information. Instead of being efficiently retrieved in grouped queries, each request individually pulls associated data like author details, reviews, and related books. What should have been a streamlined operation has turned into a burdensome load on your database, leading to longer load times and a compromised user experience.
This scenario is not unique to your online bookstore. Regardless of size or domain, many applications encounter similar performance bottlenecks due to N+1 queries. Understanding the nature of these queries, their impact on database performance, and how to optimize them is crucial for developers and database administrators. Here, we'll cover N+1 queries across Postgres and MySQL environments, providing insights and strategies to turn a potential database problem into a well-optimized system.
What Is the N+1 Query Problem?
The N+1 query problem is a common database performance issue that occurs when an application performs one query to retrieve a set of records, followed by one additional query for each record to fetch related data. The name comes from making one initial query and then N additional queries, resulting in N+1 total queries for N records.
Consider an application that displays user profiles and their respective posts. The application first executes a query to fetch all users. This is the "1" in N+1. The application then performs another query for each user retrieved to fetch their posts. If there are ten users, this results in 10 additional queries (the "N" in N+1), totaling 11 queries. While this approach may seem straightforward, it becomes highly inefficient as the number of users grows.
Assume you have two tables: users and posts. Each user has multiple posts. The posts table has a foreign key that references the users table. A naive query pattern to display each user with their posts looks like this:
-- Query 1: Fetch all users
SELECT id, name FROM users;

-- For each user obtained above, execute:
SELECT content FROM posts WHERE user_id = [user_id];
Query 1 is the "1" query. The subsequent queries are the "N" queries, iterating through the user_id values. With 100 users, the total number of queries executed is 101: one to fetch all users and 100 to fetch the posts for each user. This pattern is the N+1 query problem, and it leads to performance issues as the number of users and posts grows.
N+1 Selects Problem vs N+1 Query Problem
The N+1 selects problem and the N+1 query problem describe the same underlying issue with different terminology. Both refer to the pattern where an application executes one query to fetch a parent set of records, then executes N additional queries (one per record) to fetch related data.
The "selects" phrasing is more common in Hibernate and JPA documentation, where the additional queries are typically SELECT statements. The "query" phrasing is more common in Rails, Django, and general database performance discussions. Both terms point to the same problem and the same fixes: eager loading, batching, or a well-designed JOIN.
If Hibernate documentation refers to "N+1 selects" and Rails documentation refers to "N+1 queries," they describe the same anti-pattern.
N+1 Queries in ORMs
N+1 queries appear most often in frameworks using Object-Relational Mappings (ORMs). ORMs convert application models into SQL statements, and their abstraction over the underlying SQL is exactly what makes N+1 queries easy to introduce accidentally. Developers work with objects and attributes, and the ORM quietly issues additional queries whenever a related attribute is accessed inside a loop.
The pattern looks different in each ORM, but the shape is always the same: a list of parent records is fetched, then a loop or template accesses a related attribute on each one, and the ORM fires a query per iteration. The four most common cases are covered below.
Why AI-Assisted Development Amplifies N+1 Risk
AI coding assistants and agents can introduce and spread N+1 patterns. Tutorials, Stack Overflow answers, documentation and similar resources tend to show the straightforward loop-and-access pattern to demonstrate "how do I show a user's posts." A model predicting plausible code likely reproduces the more common shape by default. Natural-language requests also do not specify performance intent. If someone asks "for each user, show their posts," the code that literally satisfies that sentence is a loop. Eager loading requires anticipating a need the requester did not state. A human developer who has been burned by N+1 before adds .includes or prefetch_related out of habit; a model may easily miss that unless the prompt clearly asks for it.
The pattern also gets easier to miss once it exists. Agents propagate what is already there. If one view in a codebase uses lazy access, an agent extending a similar feature nearby will often imitate that existing style rather than introduce a different one, so one instance becomes several. Volume and speed outpace review habits: a developer typing a loop by hand often notices mid-keystroke "this is inside a loop, is that a query?" An agent generates the whole model, view, and template in one pass, and the person reviewing the diff is checking "does this work" rather than tracing every attribute access for a hidden query. The ORM abstraction already disguises user.posts as a plain attribute instead of a database call, and AI-generated code frequently adds another layer on top (a helper method, a serializer, a service object) that further hides where the query lives.
The upshot is that detection tooling matters more in an AI-assisted codebase, not less. Query-level analysis that surfaces high-frequency patterns after the fact catches what neither the generator nor the reviewer saw at write time.
Rails ActiveRecord
In Rails, N+1 queries commonly appear when a view iterates over a collection and accesses an associated model. The ORM lazily loads the association, firing a query per iteration:
# Controller
@users = User.all

# View (each iteration fires a query for user.profile)
<% @users.each do |user| %>
  <%= user.profile.bio %>
<% end %>
The fix in Rails is includes, which uses eager loading to fetch the associated profiles in one additional query rather than N:
@users = User.includes(:profile).all
Django ORM
In Django, an N+1 problem shows up when the application accesses related objects inside a loop without prefetching them first. Each attribute access triggers a separate database query:
# views.py
from django.shortcuts import render
from .models import User

def user_list(request):
    users = User.objects.all()
    user_profiles = []
    for user in users:
        profile = user.profile  # This creates the N+1 problem
        user_profiles.append((user, profile))

    context = {'user_profiles': user_profiles}
    return render(request, 'user_list.html', context)
Django provides two methods to fix N+1 queries. select_related is used for one-to-one and foreign key relationships and generates a SQL JOIN. prefetch_related is used for reverse foreign keys and many-to-many relationships and uses a second query with an IN clause.
Hibernate and JPA
In Hibernate and JPA, N+1 queries typically come from lazy loading of associations. The default fetch strategy for @OneToMany and @ManyToMany is LAZY, which means accessing the collection triggers a separate query per parent entity:
@Entity
public class User {
    @Id
    private Long id;

    @OneToMany(mappedBy = "user")
    private List<Post> posts;
}

// Iterating triggers one query per user for their posts
List<User> users = entityManager
    .createQuery("SELECT u FROM User u", User.class)
    .getResultList();
for (User user : users) {
    user.getPosts().forEach(post -> System.out.println(post.getContent()));
}
The standard fix in Hibernate and JPA is a JOIN FETCH or an entity graph, which loads the related collection in the initial query:
List<User> users = entityManager
    .createQuery("SELECT u FROM User u JOIN FETCH u.posts", User.class)
    .getResultList();
Prisma
In Prisma, N+1 queries appear when the application fetches a list of records and then accesses relations inside a loop without including them in the initial query:
// N+1 problem
const users = await prisma.user.findMany()
for (const user of users) {
  const posts = await prisma.post.findMany({ where: { userId: user.id } })
}
The fix in Prisma is to use include in the initial query, which fetches related records in the same request:
const users = await prisma.user.findMany({
  include: { posts: true },
})
Because ORMs abstract away the underlying SQL, developers often don't realize their code is generating inefficient N+1 queries until performance monitoring flags the pattern.
The Impact of N+1 Queries on Performance
N+1 queries impact performance, especially in large-scale systems. These queries lead to inefficient data retrieval, increased load on the database, and, ultimately, a poor user experience. Understanding the consequences of N+1 queries is crucial for database optimization.
Increased Database Load
Each additional query in an N+1 problem adds to the load on the database. This is particularly problematic with large datasets. For instance, if an application retrieves 1000 users and makes a separate query for each user's posts, it results in 1001 queries hitting the database instead of potentially just one. This extra load can slow down the database response times, affecting all application users.
Imagine a web application displaying a list of users and their recent activities. Without optimization, fetching 1,000 users might result in 1,001 queries (one to fetch all users and 1,000 to fetch activities for each). This heavy load can lead to longer wait times for the data to load, affecting user experience.
A high volume of queries also consumes more CPU and memory resources on the database server. In our previous example, instead of a single, efficient query, the server must process 1,001 queries, consuming more resources. This impacts the query in question and affects the overall efficiency of the database server, hindering its ability to handle other requests.
Scaling Challenges
Applications with N+1 query problems often struggle to scale. As the data grows, so does the number of queries. In a social media app, for example, as more users join and create posts, the N+1 issue exacerbates, leading to an exponential increase in queries. This scaling challenge can cause significant performance degradation over time, requiring more hardware resources to maintain the same level of performance.
The total time complexity for the N+1 queries pattern is O(N). As the number of records (N) increases, the total number of queries increases linearly. This linear growth can lead to significant performance degradation, especially with large datasets. Each query incurs a certain amount of overhead due to network latency, query parsing, execution planning, and data retrieval. This overhead, multiplied by the number of queries, can substantially affect performance.
Poor User Experience
The cumulative effect of these performance issues can result in longer loading times for users, negatively impacting the user experience. In an e-commerce site, if product details are fetched with N+1 queries, each additional millisecond in load time can potentially lead to lost sales as customers grow impatient and leave the site.
Consider a real-time data dashboard that monitors and displays various metrics. If each metric's data is fetched using separate queries for each element, the dashboard will experience noticeable delays, failing to deliver the real-time experience expected by users.
How to Detect N+1 Queries
The simplest way to detect N+1 queries is often through careful code review. Reviewers look for loops or iterative processes that make database calls, particularly in the context of ORMs or when accessing related data.
N+1 queries can be subtle in complex applications, so several tools help surface the pattern. The rest of this section covers the most useful ones.
Rank Costly Queries with RDST
RDST is Readyset's free command-line tool for analyzing query performance on Postgres and MySQL databases. On a codebase with a hidden N+1 pattern, rdst surfaces the pattern as a cluster of near-identical queries at the top of the load ranking, along with per-query cost and total contribution to database load.
RDST uses an LLM-assisted analysis layer to explain why queries are slow and to suggest fixes. All state is stored locally in ~/.RDST, and by default RDST does not send query contents, schemas, or database internals to external servers. RDST supports Postgres and MySQL across a wide range of providers and runs on macOS, Linux, and Windows.
To install rdst, run:
curl -fsSL https://downloads.readyset.io/packages/rdst-cli/install.sh | sh
Getting started documentation is available here.
Postgres Query Logging
Enabling query logging in Postgres is a common starting point for detecting N+1 query problems. Logging all executed queries allows analysis of the logs for patterns that indicate N+1 issues.
-- Set the logging level to log all statements
ALTER DATABASE your_database_name SET log_statement = 'all';
After enabling logging, look for sequences of similar queries that differ only in a parameter, such as multiple queries fetching details for different user IDs:
2024-01-23 10:00:01 UTC LOG:  statement: SELECT * FROM users
2024-01-23 10:00:02 UTC LOG:  statement: SELECT * FROM posts WHERE user_id = 1
2024-01-23 10:00:02 UTC LOG:  statement: SELECT * FROM posts WHERE user_id = 2
2024-01-23 10:00:02 UTC LOG:  statement: SELECT * FROM posts WHERE user_id = 3
2024-01-23 10:00:02 UTC LOG:  statement: SELECT * FROM posts WHERE user_id = 4
2024-01-23 10:00:02 UTC LOG:  statement: SELECT * FROM posts WHERE user_id = 5
...
A long sequence of similar queries with only a parameter changing is a strong indicator of N+1 queries.
MySQL Query Logging and Performance Schema
MySQL provides two mechanisms for detecting N+1 patterns. The slow query log captures queries exceeding a latency threshold, but N+1 queries are usually fast individually, so the slow query log often misses them. The general query log captures every query and works better for spotting N+1 patterns, though it produces high log volume:
-- Enable the general query log
SET GLOBAL general_log = 'ON';
SET GLOBAL general_log_file = '/var/log/mysql/general.log';
For production analysis, MySQL Performance Schema is the safer approach. The events_statements_summary_by_digest table groups queries by normalized shape and shows execution count, total latency, and average latency per shape. An N+1 pattern appears as a single row with an unusually high count:
SELECT digest_text, count_star, sum_timer_wait/1e9 AS total_ms
FROM performance_schema.events_statements_summary_by_digest
ORDER BY count_star DESC
LIMIT 20;
The pt-query-digest tool from Percona Toolkit provides similar aggregation over MySQL slow query logs and is another common way to detect repeating query patterns in MySQL environments.
Performance Monitoring Tools
Tools like pgBadger (Postgres), DataDog, and ScoutAPM offer detailed insights into database performance and can identify inefficient query patterns that suggest N+1 issues.
With pgBadger, Postgres logs are analyzed to produce a report highlighting frequently executed queries. A high frequency of similar queries is a signal of N+1 problems.
| Rank | Query Pattern | Executions | Avg Duration | Total Duration |
|---|---|---|---|---|
| 1 | SELECT * FROM users | 10 | 15ms | 150ms |
| 2 | SELECT * FROM posts WHERE user_id = ? | 850 | 5ms | 4250ms |
| 3 | UPDATE posts SET ... WHERE post_id = ? | 50 | 20ms | 1000ms |
| 4 | SELECT * FROM comments WHERE post_id = ? | 300 | 4ms | 1200ms |
A common pgBadger finding is a SELECT * FROM posts WHERE user_id = ? query with a very high execution count. If SELECT * FROM users executes 10 times and the follow-up posts query executes 850 times, the disparity is a classic N+1 signature. Each individual posts query may run in a few milliseconds, but the cumulative time is significant.
Application performance monitoring tools like DataDog and ScoutAPM automatically flag N+1 patterns and show the response times, call counts, and query text.
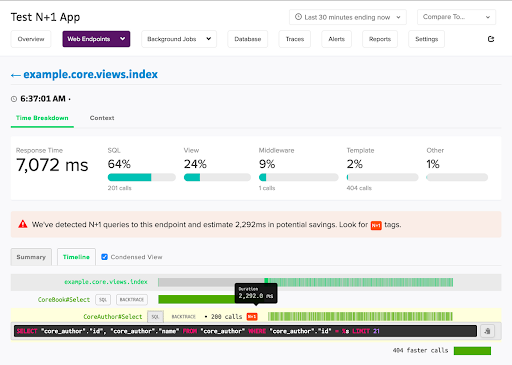
Languages also provide profiling tools that help surface excessive database calls. Python's cProfile shows where the application spends its time, and a large amount of time in database-related functions can indicate N+1 queries:
import cProfile
cProfile.run('function_that_loads_data()')
Most ORMs also allow enabling SQL debug logging, which logs every SQL query the ORM executes. In Django, setting DEBUG = True in settings.py makes all SQL queries available via connection.queries during development.
EXPLAIN Command
The EXPLAIN command in Postgres and MySQL shows the query execution plan and helps identify queries that do not efficiently use indexes or perform full table scans. Full table scans repeated across an N+1 pattern are especially expensive:
EXPLAIN SELECT * FROM posts WHERE user_id = 1;
The output provides insights into how the database is executing the query:
QUERY PLAN
-----------------------------------------------------------
 Seq Scan on posts  (cost=0.00..35.50 rows=1560 width=2048)
   Filter: (user_id = 1)
A "Seq Scan" indicates a sequential scan of the posts table, which is generally less efficient than an index scan. For a single query this may be acceptable, but when similar queries execute repeatedly for different user_id values in an N+1 pattern, the database performs numerous full table scans and degrades performance significantly. The absence of an index scan often means there is no index on the user_id column, or the query planner did not find it efficient to use.
How to Fix N+1 Queries
The N+1 pattern can be resolved through better query design, eager loading, or caching. Each approach fits different situations.
Eager Loading
When using ORMs, eager loading is usually the best solution. Eager loading fetches all related data in a single additional query instead of separate queries for each record. Rails uses .includes, Django uses select_related and prefetch_related, Hibernate and JPA use JOIN FETCH or entity graphs, and Prisma uses include.
An optimized Django example using both select_related and prefetch_related:
# views.py
from django.shortcuts import render
from .models import User

def user_profiles(request):
    # select_related fetches the one-to-one Profile in the same query
    users = User.objects.select_related('profile').all()

    # prefetch_related handles reverse ForeignKey relationships
    users = users.prefetch_related('posts')

    return render(request, 'user_profiles.html', {'users': users})
The select_related('profile') method fetches the associated Profile for each User in the same database query, avoiding a separate query per user. The prefetch_related('posts') method performs one additional query for all posts and efficiently pairs them with users. Together they collapse the N+1 pattern into a small, fixed number of queries.
Query Design
When not using an ORM, queries can be optimized directly. A few practices reduce N+1 patterns and other query inefficiencies:
- Use joins appropriately. A SQL JOIN combines data from multiple tables in a single query. Understanding the differences between
INNER JOIN,LEFT JOIN, and other join types is essential for choosing the right one and avoiding unnecessary data retrieval. - Select only required columns. Specify the columns you need in
SELECTstatements rather than usingSELECT *. This reduces the amount of data transferred and processed. - Use indices deliberately. Queries should leverage indices on columns used in
JOIN,WHERE, andORDER BYclauses. - Avoid looping queries. Any place code iteratively executes queries in a loop is a candidate for refactoring to bulk retrieval. Replace multiple small queries with fewer, more comprehensive queries.
- Limit data with pagination. For large datasets, pagination limits the data retrieved and processed in a single query.
The naive N+1 query pattern from earlier can be rewritten as a single JOIN that fetches all users and their posts in one round trip:
SELECT u.id, u.name, p.content
FROM users u
LEFT JOIN posts p ON u.id = p.user_id;
Caching Repeating Queries
When N+1 queries have already been eliminated through eager loading or better SQL, and specific read-heavy queries still dominate database load, caching removes them from the database path entirely. Cached results are served in-memory at sub-millisecond latency, and repeat reads no longer reach the primary database.
Readyset is a SQL-native caching layer for Postgres and MySQL that connects to the primary database through its replication stream. Cached results in Readyset stay current with the underlying data automatically as writes flow through the replication stream. This removes the manual invalidation logic that traditional cache layers require.
Readyset supports three approaches to caching, each suited to different workload characteristics.
QueryPilot is the Readyset layer that automatically identifies high-impact queries and caches them without manual configuration. QueryPilot observes traffic through the Readyset proxy, tracks query frequency and latency, and promotes hot queries to cache. QueryPilot selects between deep and shallow caching automatically based on query structure. QueryPilot also coalesces identical in-flight requests for uncached queries into a single upstream execution, eliminating stampede amplification on cache misses.
Deep cache in Readyset uses incremental view maintenance to keep query results strictly consistent with the primary database. Writes flow through the replication stream, and deep-cached views update automatically as underlying rows change. Deep cache in Readyset fits workloads that require strong freshness guarantees, and cached queries typically return in sub-millisecond time.
Shallow cache in Readyset uses TTL-based strategies for broader cache coverage on workloads where slightly stale data is acceptable in exchange for higher hit rates. Shallow cache in Readyset manages refreshes, coalescing, and background updates automatically, without application-level TTL management.
All three deploy as a drop-in proxy. The application connection string points at Readyset instead of the primary database, and no application code changes are required. Readyset works with any ORM that already speaks Postgres or MySQL.
Readyset customers have measured 10x to 100x faster queries on cached reads, 30 to 85%+ reductions in database load, and up to 70% reductions in infrastructure costs. One example is ClickFunnels, who reduced their Aurora MySQL read replica workloads by over 85% with Readyset.
To cache a query manually in Readyset, prepend CREATE CACHE FROM to the query:
CREATE CACHE FROM SELECT content FROM posts WHERE user_id = ?;
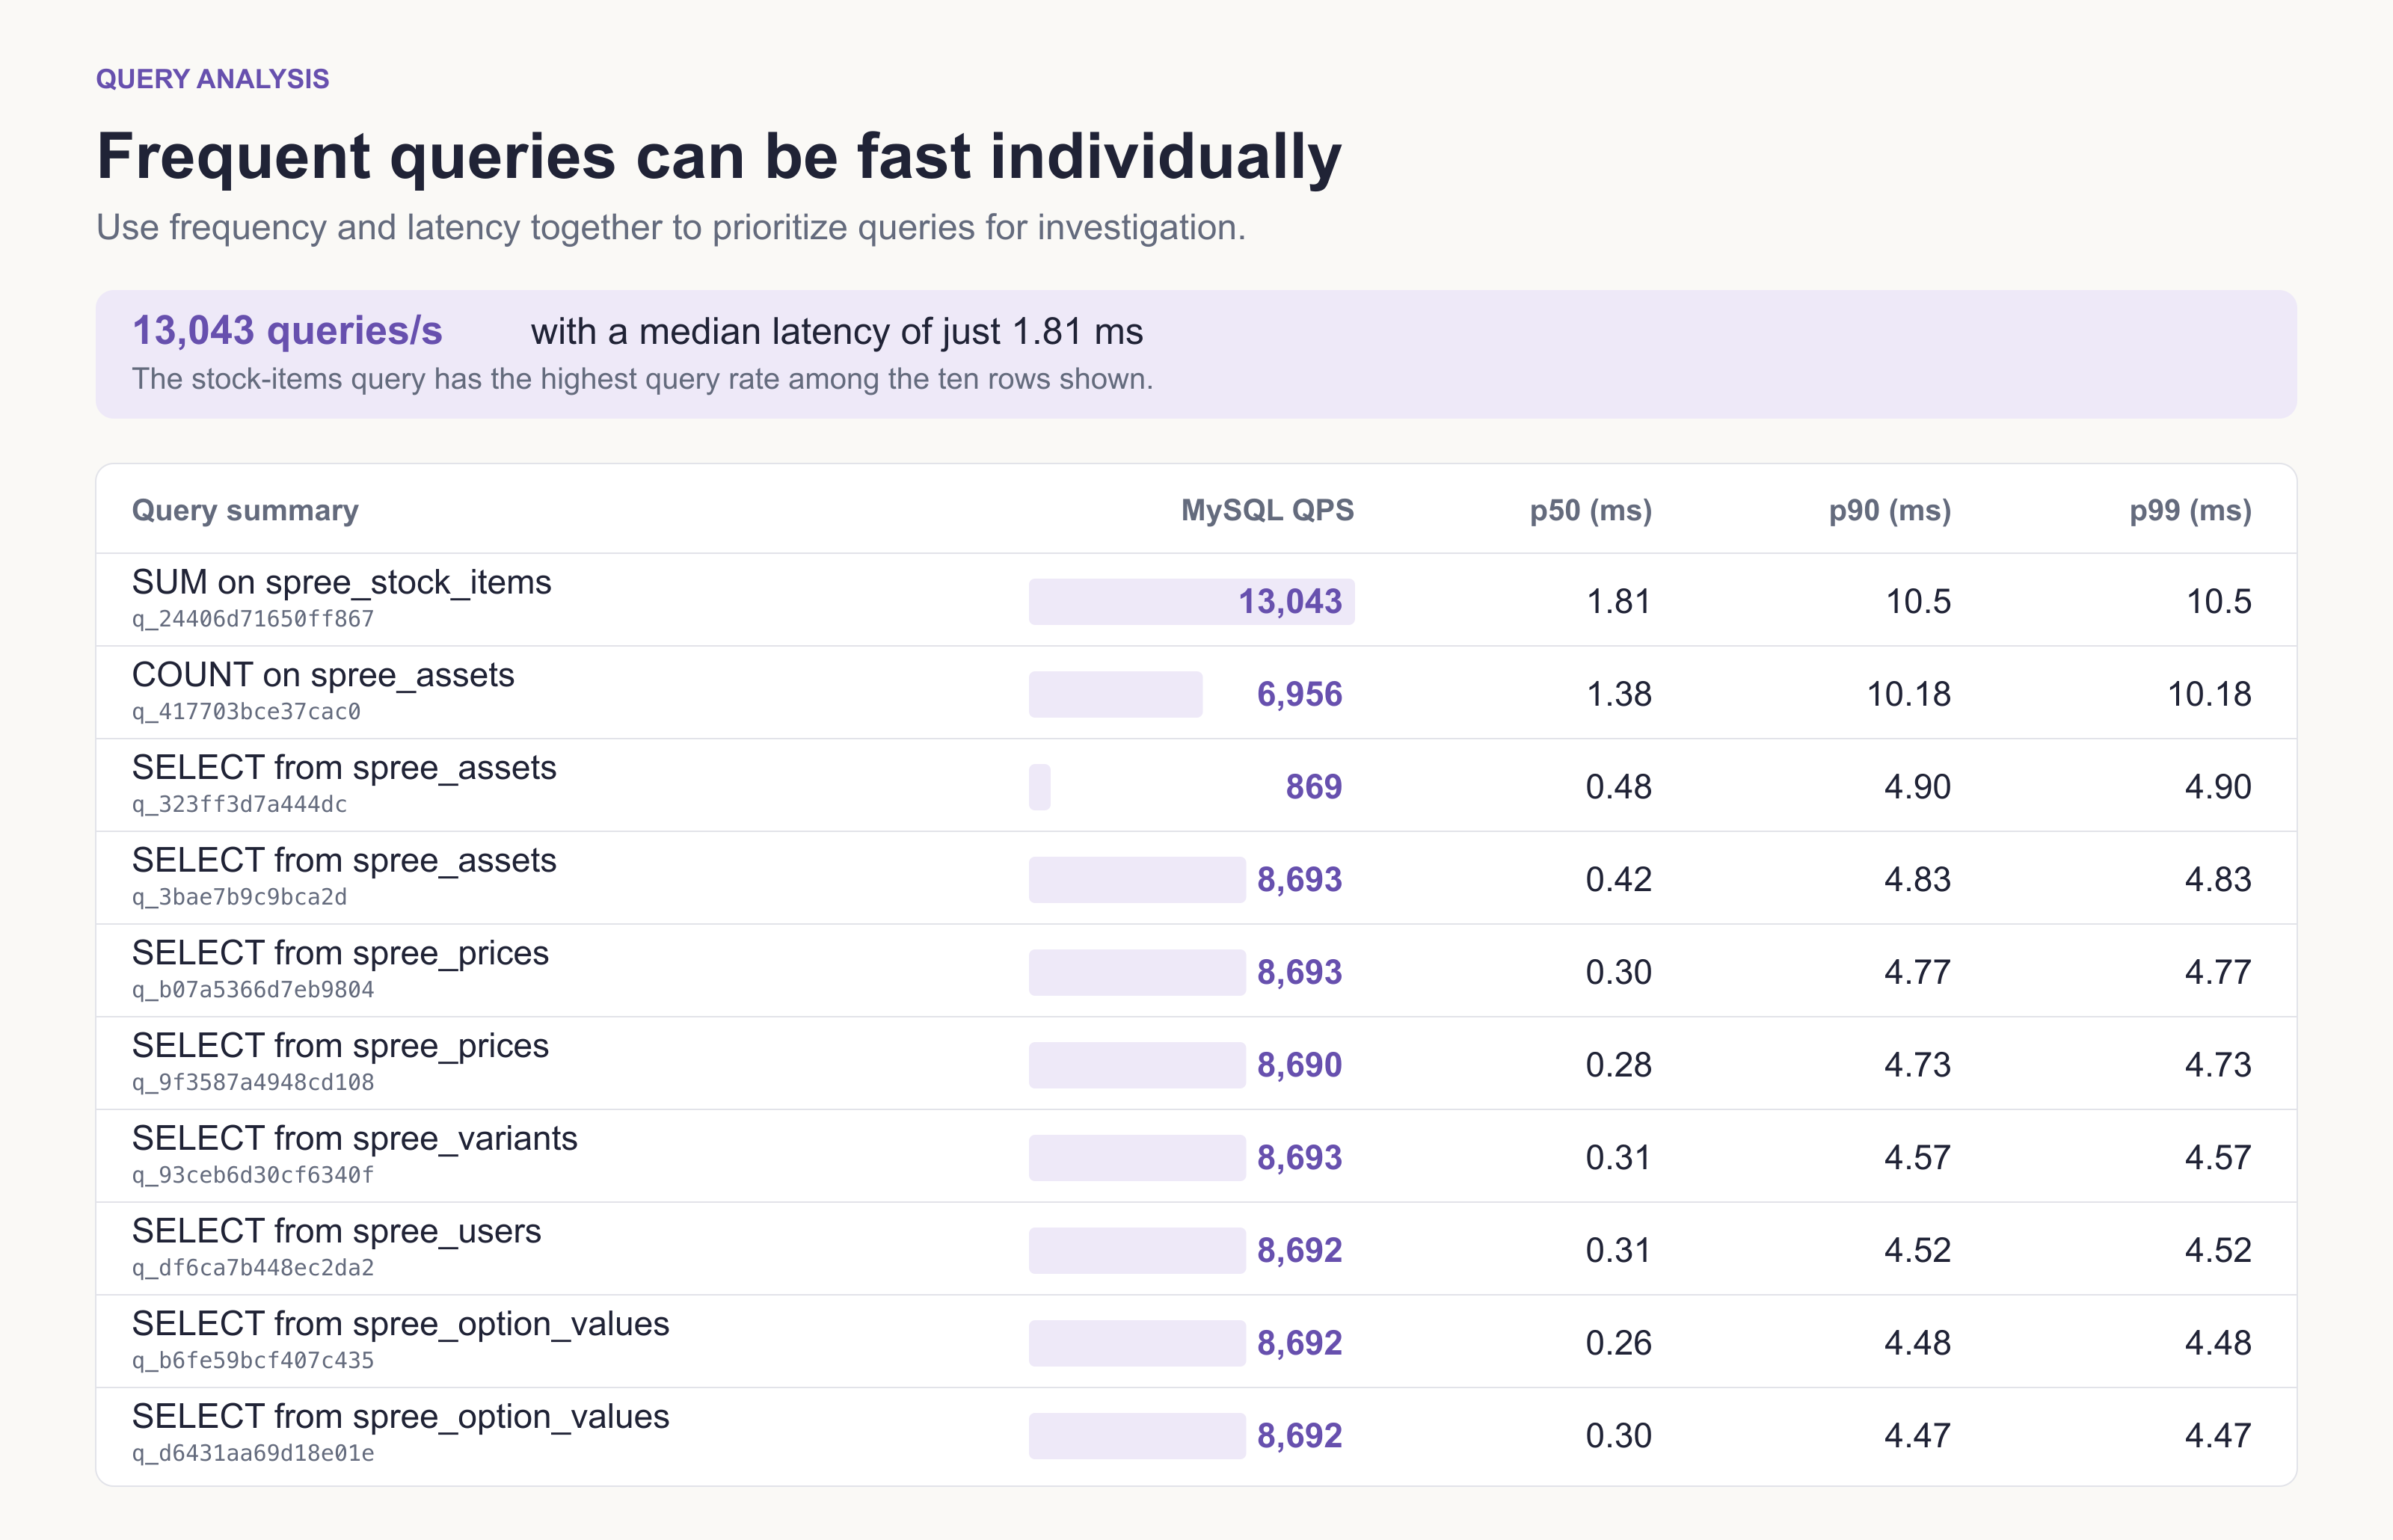
Results from this query are served from Readyset with sub-millisecond latency, and Readyset keeps the cached result current from the primary database's replication stream. Cached results update automatically whenever underlying data changes.
Next Steps
N+1 queries can destroy application performance as it scales, and ORMs often hide the pattern from developers until performance monitoring flags it. Once the pattern is visible, eager loading and better query design usually resolve it. For queries that dominate database load after the N+1 pattern is fixed, caching removes them from the database path entirely.
The fastest way to see whether N+1 patterns or other repeating queries are driving database load is to run RDST against a Postgres or MySQL database. RDST is free, runs locally, stores all state on the developer machine and is available under the Apache 2.0 license.
Related articles
Continue reading more about postgresql.
PostgreSQL Rishi Raj Jain
Getting started with Django, PostgreSQL, and Readyset
Real-world applications face performance challenges with growing data and user traffic. Caching mitigates these challenges by storing frequently accessed data, reducing database fetches, improving response times, and enhancing application scalability, reliability, and user experience. Readyset is a caching engine for Postgres and MySQL databases, requiring minimal adjustments to existing setups. Its wire-compatible design means that the only modification necessary is to adjust the connection st
Rishi Raj Jain2024-05-1611 min read
PostgreSQLReadyset
Optimizing SQL Pagination in Postgres
SQL pagination is a technique to retrieve a subset of records from a Postgres table or result set. It allows you to divide large datasets into smaller, manageable chunks called "pages" and retrieve them one page at a time. Understanding Pagination in Postgres Pagination is commonly used in applications that display data in a paginated format, such as search results, product listings, or user records. It helps improve performance and user experience by loading and displaying only a portion o
2024-04-2413 min read
PostgreSQL Marcelo Altmann
Mastering Query Rewriting for Faster PostgreSQL Performance
When you first spin up your app, the emphasis is on getting started and getting data to your clients. But when you don’t have throughput, you are also not going to have enough concurrency to unveil bad queries. But then you have success. And success means data. More users, more interactions, more everything. Suddenly, queries that performed fine are struggling under the load, hurting performance and scalability. This is all going to mean a far worse user experience when much higher costs becaus
Marcelo Altmann2024-04-119 min read